Someone will ask what your AI does when it is wrong.
A customer security questionnaire, a release next month, a model change you did not schedule. We test the live AI feature by hand and give you a dated report, plus a one-page attestation you can attach.
Fixed prices from 700 USD. The reply says what can be tested, what cannot, which product fits, or that none does, and names the turnaround.
Arrived here from a note about your product? What you received was an unsolicited assessment of your public AI surface: one finding, reproduction steps, and nothing held back to create leverage. If the finding did not hold up, the note said so.
This page is what the paid work looks like: the same method, on the surfaces only you can give access to, with the documents your buyers ask for.
"Has the system undergone AI red teaming? Provide summary findings and remediation status."
Three products, each defined by what you need it for
Fixed price for a narrow result. No hourly billing, no retainer before the first delivery.
Questionnaire pack
- You get
- A one-page attestation sheet, a framework map with editions (OWASP Top 10 for LLM Applications, OWASP Top 10 for Agentic Applications), and the full report for internal use.
- Written for
- The field in a corporate AI security questionnaire that reads "Has the system undergone AI red teaming? Provide summary findings and remediation status."
- We need from you
- The URL of the AI feature and the page that promises what it does. A test account if the feature sits behind a login.
Pre-release gate
- You get
- A probe set built from your own documentation, run against the release candidate. A defect log in ISTQB form. "What regressed", in three lines.
- Written for
- The week before a release, a provider swap, or a model version bump, when nobody wants to find out from a customer.
- We need from you
- Access to the staging or release candidate, the current documentation, and the date.
Regression set you own
- You get
- A corpus with confirmed reference answers, the probe set, a runner script, a written procedure, and a dated re-test attestation. It stays with you and runs without us.
- Written for
- A team that will ship changes to the same AI feature for a year and wants every release measured against the same standard.
- We need from you
- API or interface access, the documentation, and one person on your side to run it once with us.
Every document is dated. Instead of a validity period you get a re-test you can run again after a release or a model change, because behaviour that depends on a model can change without a release of your product.
What this finds
Three findings from unsolicited assessments of public AI surfaces. No company is named here, and none will be.
A support agent undersold its own product
A public support agent quoted a monthly plan about 29 percent below the price published on the same site, in three separate conversations with different wording. When the published figure was put to it, the agent rejected it and said it had checked the source.
A scanner allowed what its own docs ban
On both communities tested with no published rule on the subject, a checker returned an allow verdict, where its own documentation says a missing rule must be treated as a refusal. Four communities that did publish a rule were read correctly, so the defect is one branch, not the engine. The wrong verdict then became the input to the next tool, which passed the text.
An agent filled a gap instead of asking
An assistant asked to create an alert, with the destination left out of the request, invented an external one and created the alert, in three runs of four. The fourth asked where to send it and warned that a webhook leaves the system. A blocked local address was treated as a routing problem to solve rather than a stop.
All three were found the same way: take what the product promises in its own published material, then hold the behaviour to it. None of them announce themselves as failures, which is why nobody goes looking.
How the work runs
Human-run, evidence-first, reproducible. One target at a time, and every step is written down well enough for you to run it again.
You send the surface and the promise
A pricing page, a documentation page, a support assistant, an agent with tools. Within three working days you get a scoped reply: what can be tested, what cannot, which product fits, and the turnaround.
The standard is built from your own material
Your published pages are quoted verbatim with URL and capture date. Reference answers are confirmed against your system's own storage or output. Results are read from files, APIs and the live DOM, never from a screenshot.
You get the documents, then a free re-check
Every finding ships with reproduction steps and a three-link consequence chain, each link marked observed or assumed. When you fix something, the re-check is free.
Who does the work
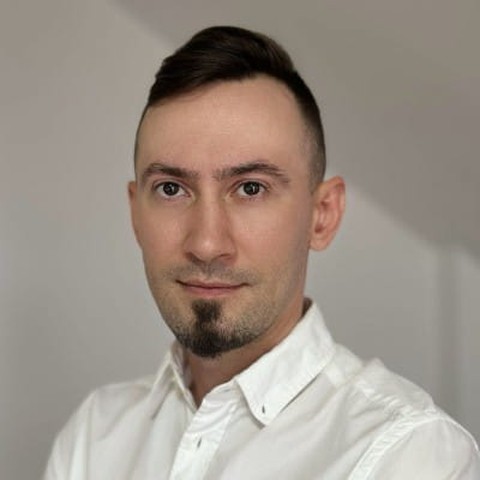
Nikita Kalachev. QA engineer, seven years and more, including 4.5 years at EPAM Systems on platforms serving over a million users. The work is done by hand, one target at a time, and the person who ran the probes writes the report and signs it. Operating through Platilus LLC, registered in Georgia. Full background, experience and CV →
CrossCheck AI is the cross-model verification tool built for this work, and the verification layer our reports pass through before they go out: three models from different providers check each claim independently, then challenge each other. It is open in public beta. Try it →
The questions buyers ask before they sign
Is one person enough?
There is no bench to scale onto next week. What that buys you is that the same person who found the thing writes the report and answers your questions about it, and that nothing is generated by a tool and passed off as human review. The full record is on the engineer page: seven years of QA, four and a half of them at EPAM, and what the tooling does not do.
How do you deal with non-deterministic output?
Model-dependent behaviour counts as reproduced only when it appears across three separate conversations with different phrasings and no shared context. A single occurrence is reported as a single occurrence, in those words. Counts are printed as counts: three of four is written as three of four, never as a percentage.
Are these just jailbreaks?
No stock jailbreak libraries are used. Every finding starts from the product's own promise, read from its live pages, and is tested against behaviour. The three findings above are the kind of thing that comes out: wrong prices, wrong verdicts, actions taken on parameters nobody supplied.
Can we cite the report in our security questionnaire?
Yes. Behavioural findings are mapped to OWASP categories with their edition, and the mapping block states in writing what citing a category does and does not mean. The attestation sheet is written for the questionnaire field, in the questionnaire's own words.
Where is this weak?
- No CI/CD integration. The probe set runs on request or by your own hand, not on every commit.
- Deterministic replay of long multi-step scenarios is partial. Short chains reproduce reliably; long ones are reported with their reproduction count and nothing stronger.
- Full execution traces are partial. What the system did is read from its own API where one exists, and from its interface where one does not.
Will my customer's security reviewer accept this?
That is what the attestation sheet is written for. It carries the assessment date, the assessor and legal entity, the scope in and out, the method, the result with reproduction counts, the OWASP categories with their edition, and a re-test commitment. Those are the items procurement guides ask for in a red-team report. What it does not carry is a claim of certification or compliance, and it says so on the sheet.
Do you sign an NDA, and what happens to what you find?
Yes, your NDA or ours, before any access is granted. Findings from paid work belong to you. Nothing from paid work is published, named, or reused as an example, here or anywhere else. The three findings on this page come from unsolicited assessments of public surfaces, and no company is named.
Do you need access to production?
No production access and none of your credentials. A test account on the live product or a staging copy, with fabricated data. Nothing is posted, sent, or purchased on your behalf, and no third-party system of yours is connected.
Is this a certification?
No. See the box below. It is an independent report of what was tested and what was found, dated, with the method described well enough to repeat.
- Not a certification, and not a statement of compliance with any standard or regulation.
- Platilus LLC is not a notified body and does not perform conformity assessment.
- Whether your system falls within Chapter III of the EU AI Act is your own determination. It is not assessed here and no article of that regulation is asserted to apply.
- Citing an OWASP category describes what was tested. It is not a check against that list in full.
- Not infrastructure penetration testing, not a scan, and not a vulnerability report.
The category this work belongs to
There is a published procurement category for what fills the questionnaire field above, with its own definition.
"Adversarial testing of AI systems to uncover safety, security, misuse, robustness, ethical, and alignment failure modes"
Send the URL. Get a scoped reply.
Received. A scoped reply within three working days.
A scoped reply within three working days. Fixed prices from 700 USD. Contract and invoice from Platilus LLC, Georgia (the country).
Prefer email: [email protected]